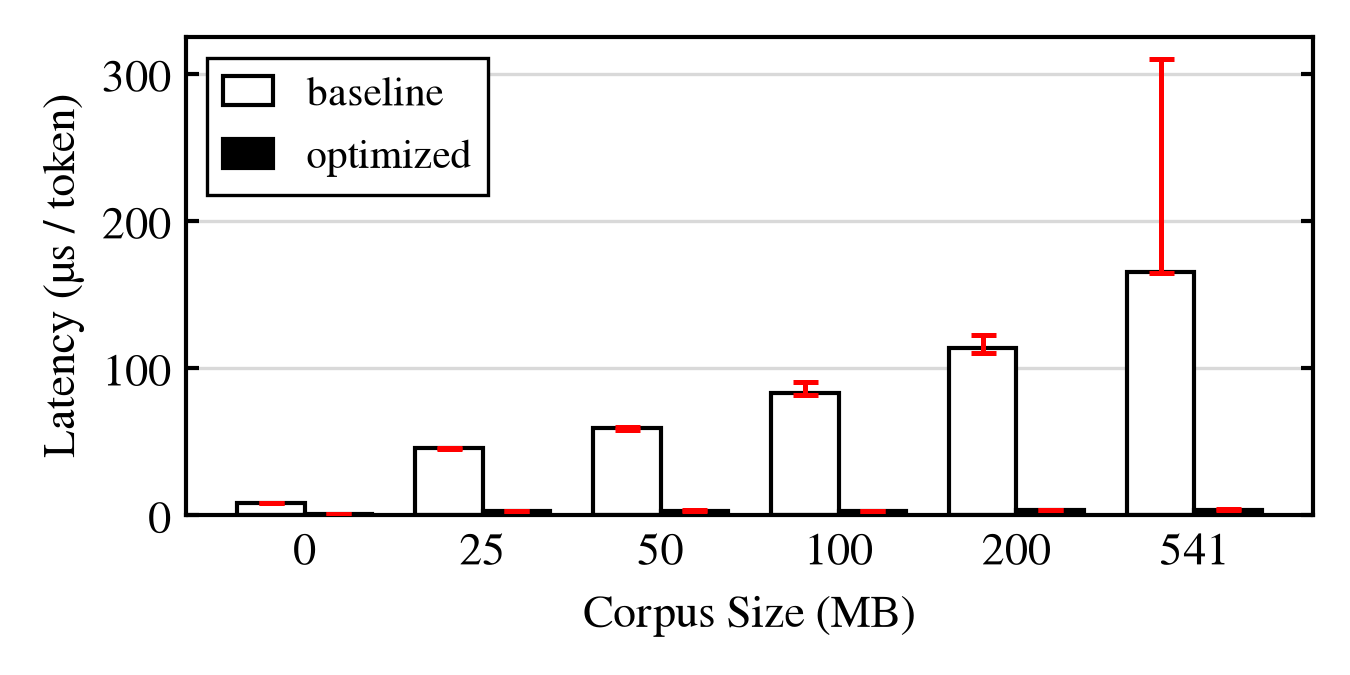
42x faster prompt lookup drafting in llama.cpp
Developers working on the open‑source LLaMA inference engine llama.cpp have introduced an optimization that speeds up the prompt‑lookup phase by roughly 42 times. The change restructures how token embeddings are accessed, reducing latency during text generation. Benchmarks show a substantial drop in processing time, potentially improving interactive applications that rely on the model for various use‑cases.