LLM Classification Is Feature Engineering
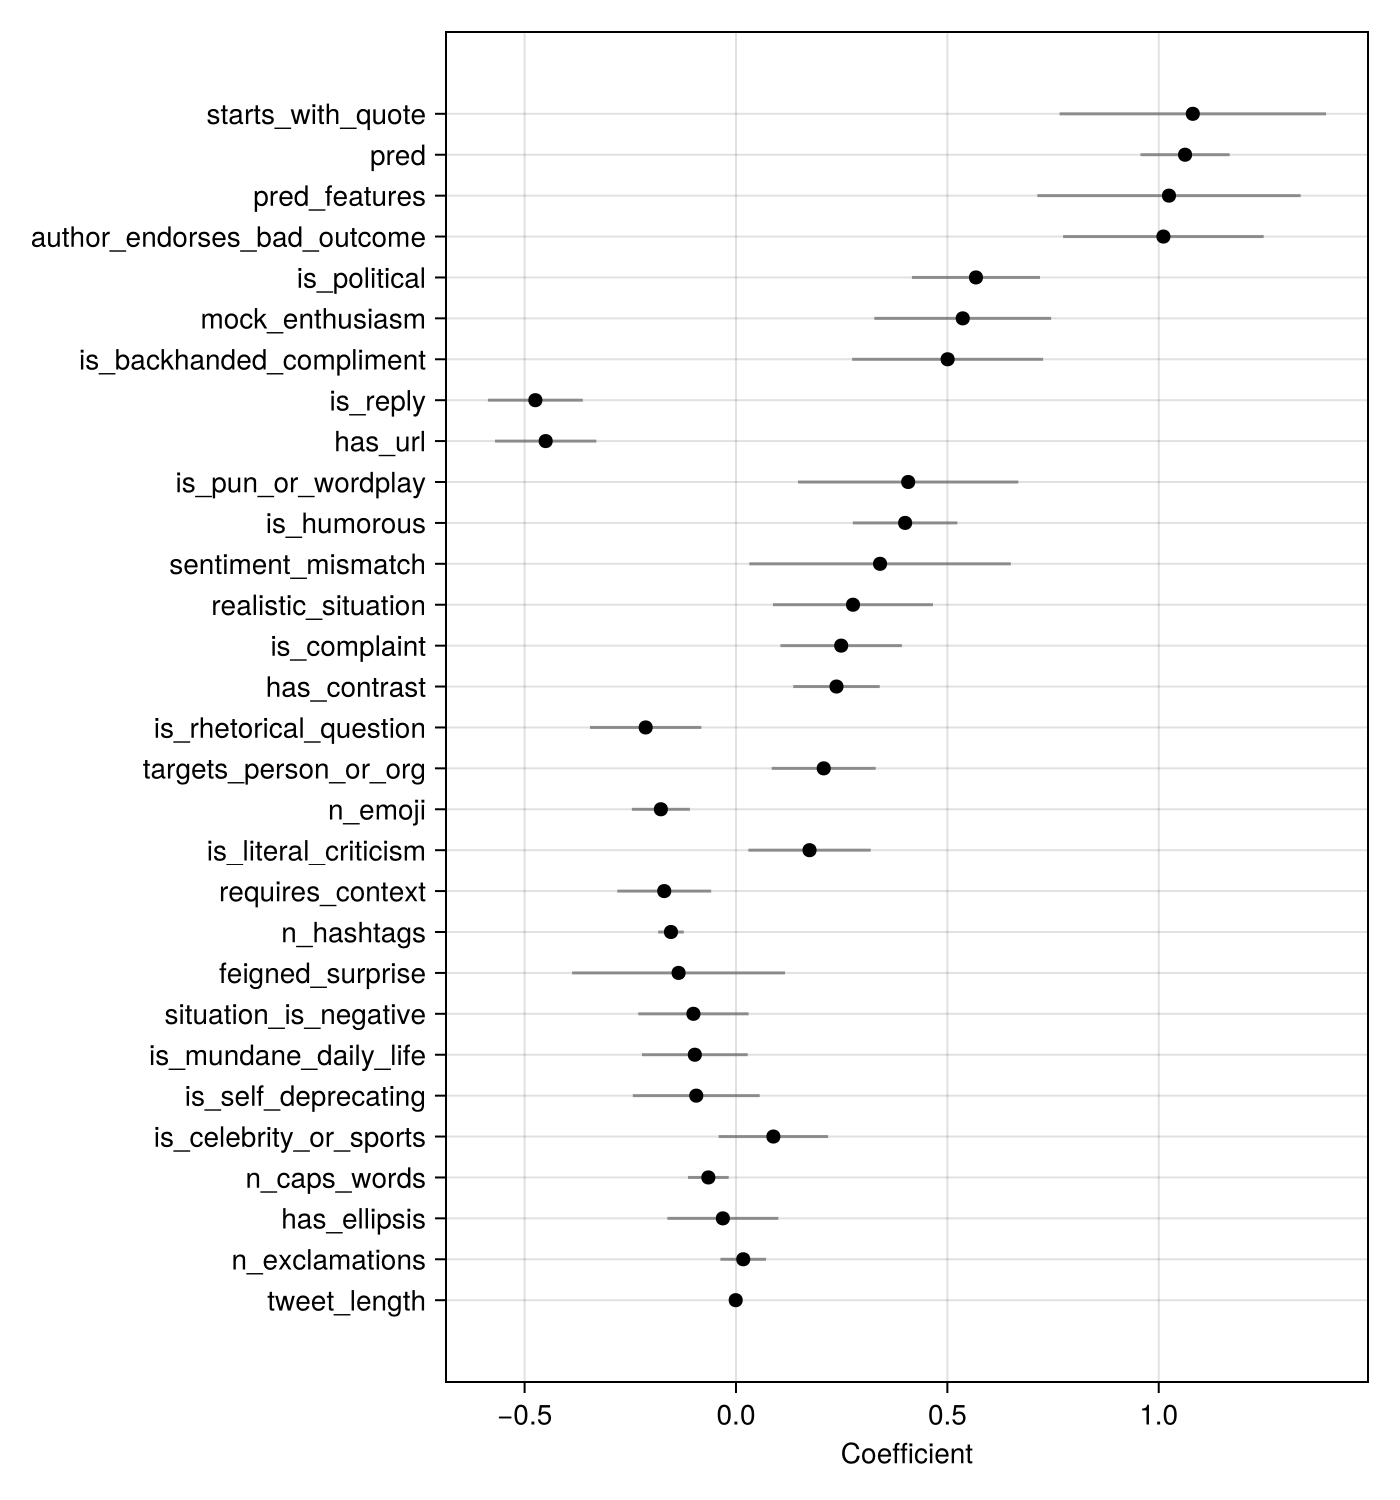
Recent discussions highlight that using large language models for text classification often reduces to traditional feature engineering. Practitioners extract embeddings or prompts from the model and feed them into downstream classifiers, rather than relying on end‑to‑end fine‑tuning. This approach emphasizes the importance of data representation choices and suggests that LLMs complement, not replace, classic feature‑based methods.