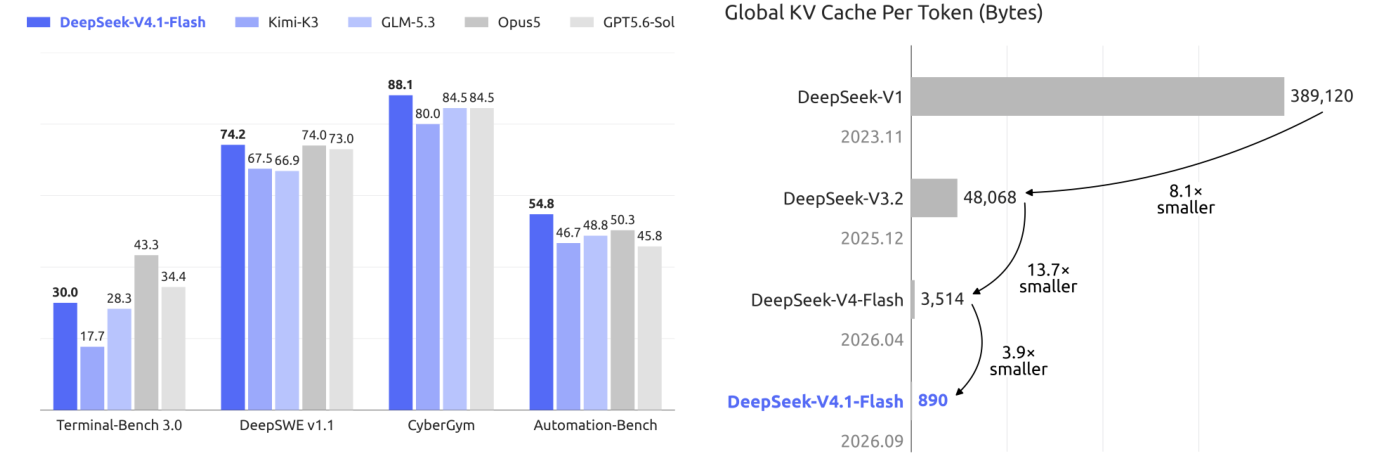
DeepSeek-v4.1 Flash: Pushing the Limits of KV Cache Compression
DeepSeek released version 4.1 Flash, a new approach that significantly reduces the size of key‑value caches used during large language model inference. By applying advanced compression algorithms, the method lowers memory consumption and speeds up generation without sacrificing output quality. The team reports benchmark improvements across several model sizes, positioning the technique as a practical tool for deploying LLMs on limited hardware.