Dust: Pretraining Transformers Without Backpropagation
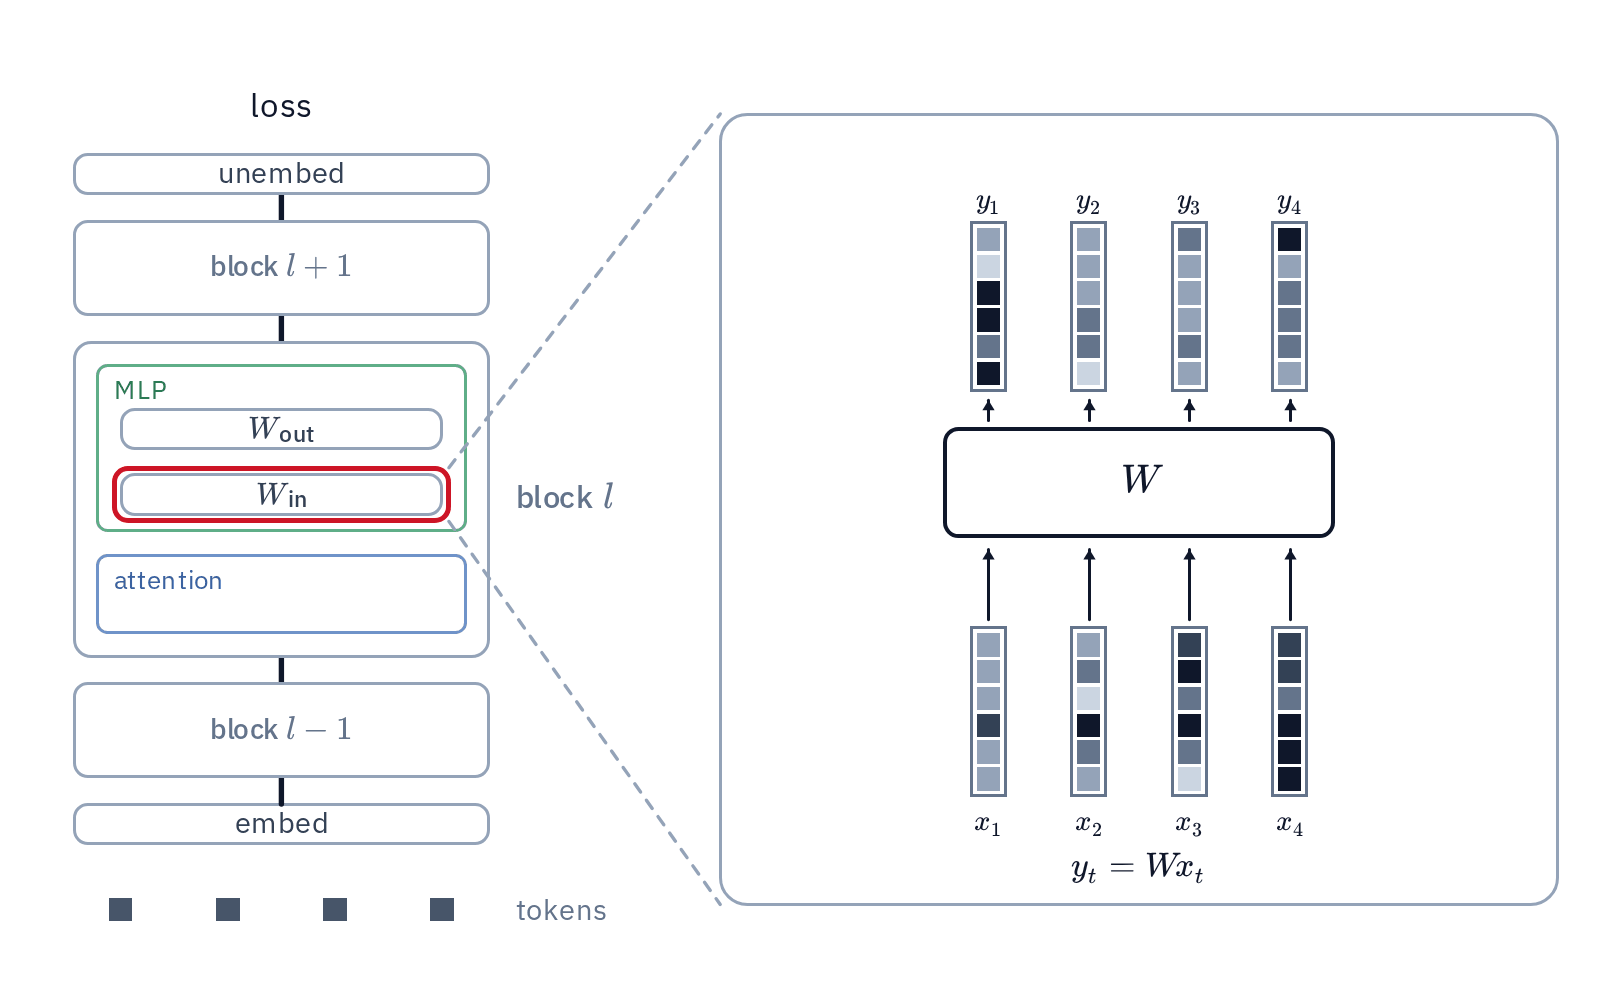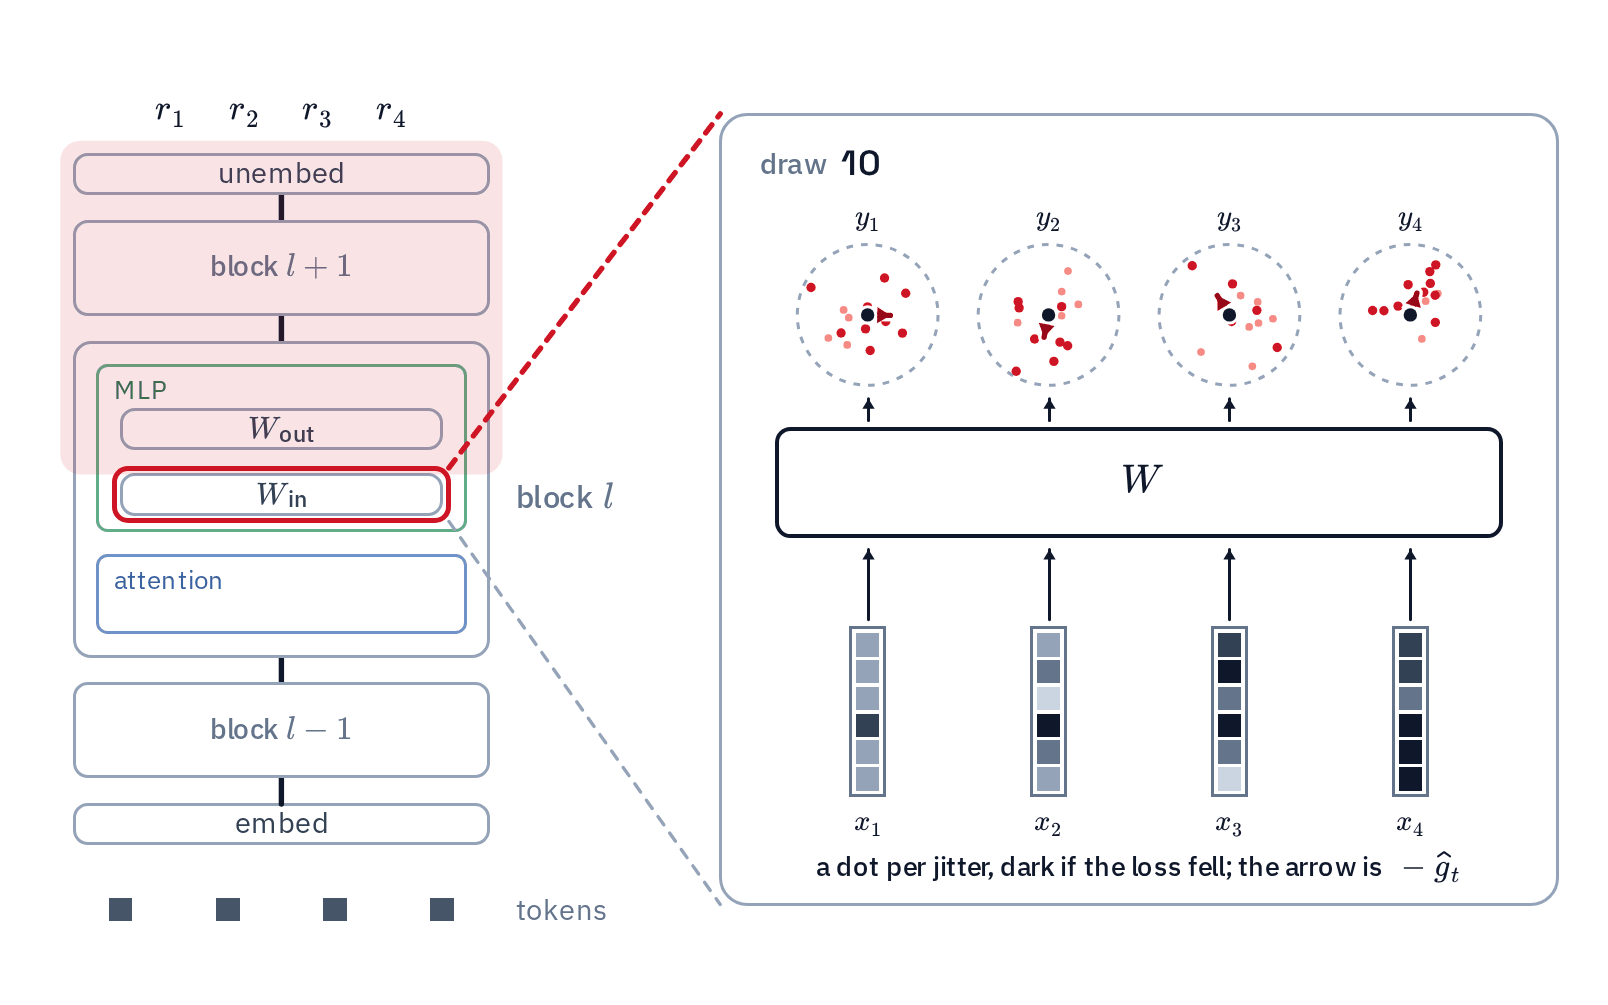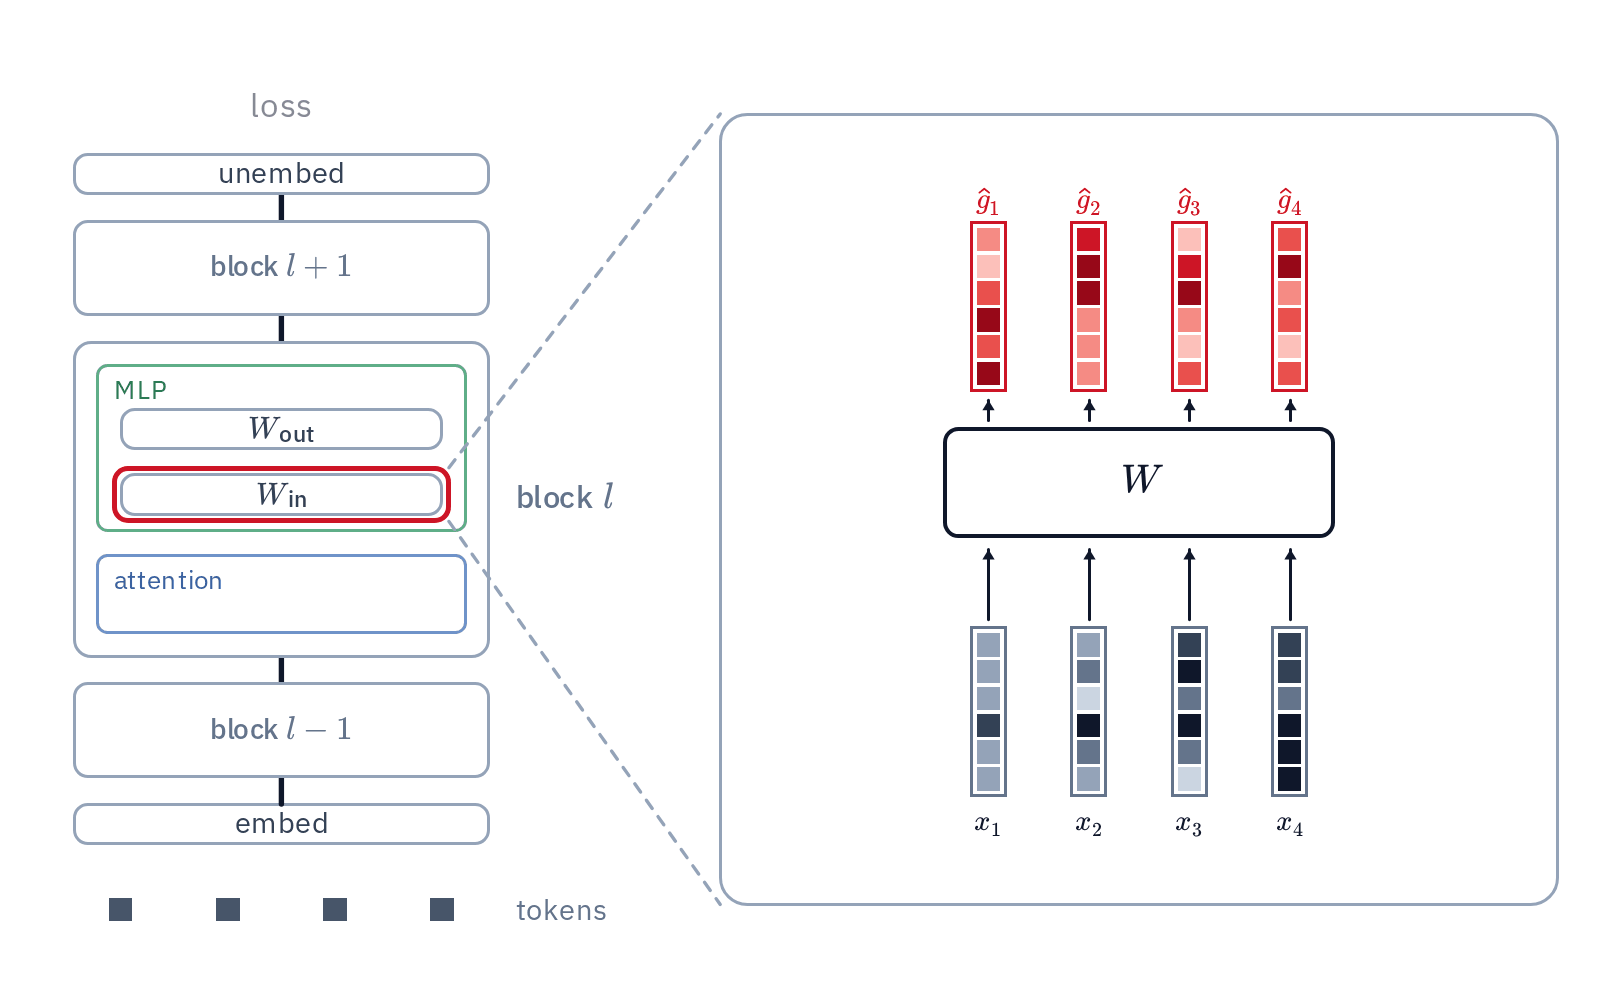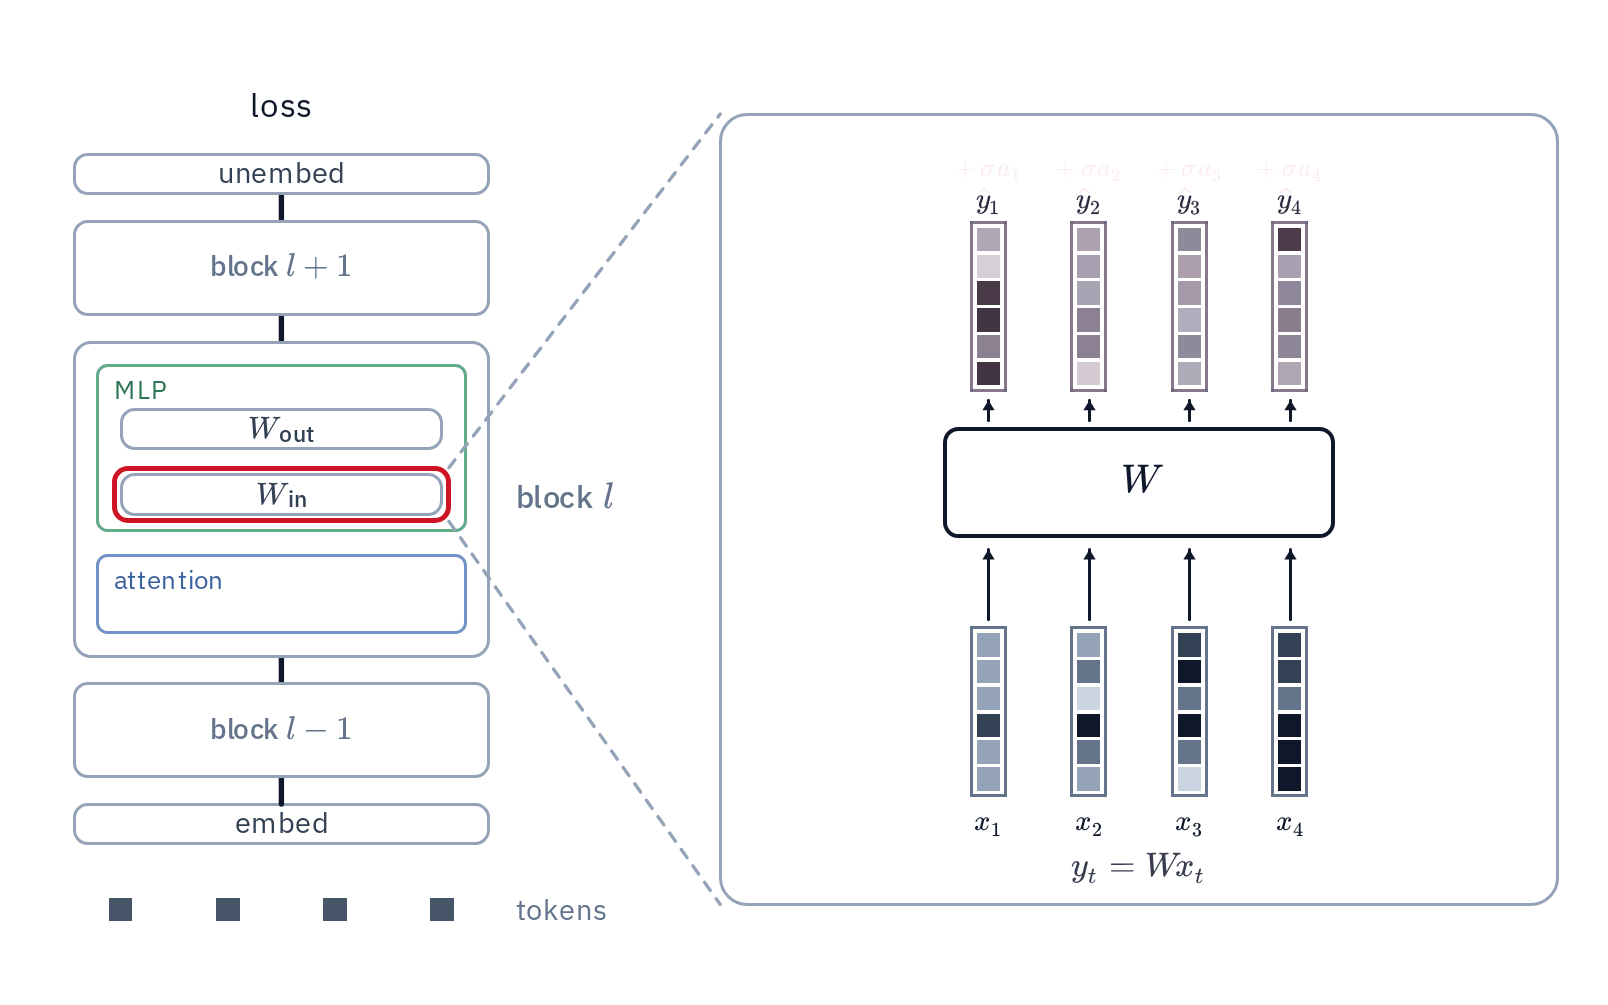
Dust introduces a new approach to pretrain transformer models without relying on backpropagation. The method uses alternative optimization techniques to update weights, potentially lowering memory demands and speeding up training. Researchers claim the technique can match or approach performance of traditional backprop-based pretraining while reducing computational overhead. The approach could make large language models more accessible.